Jekyll, One Problem at a Time
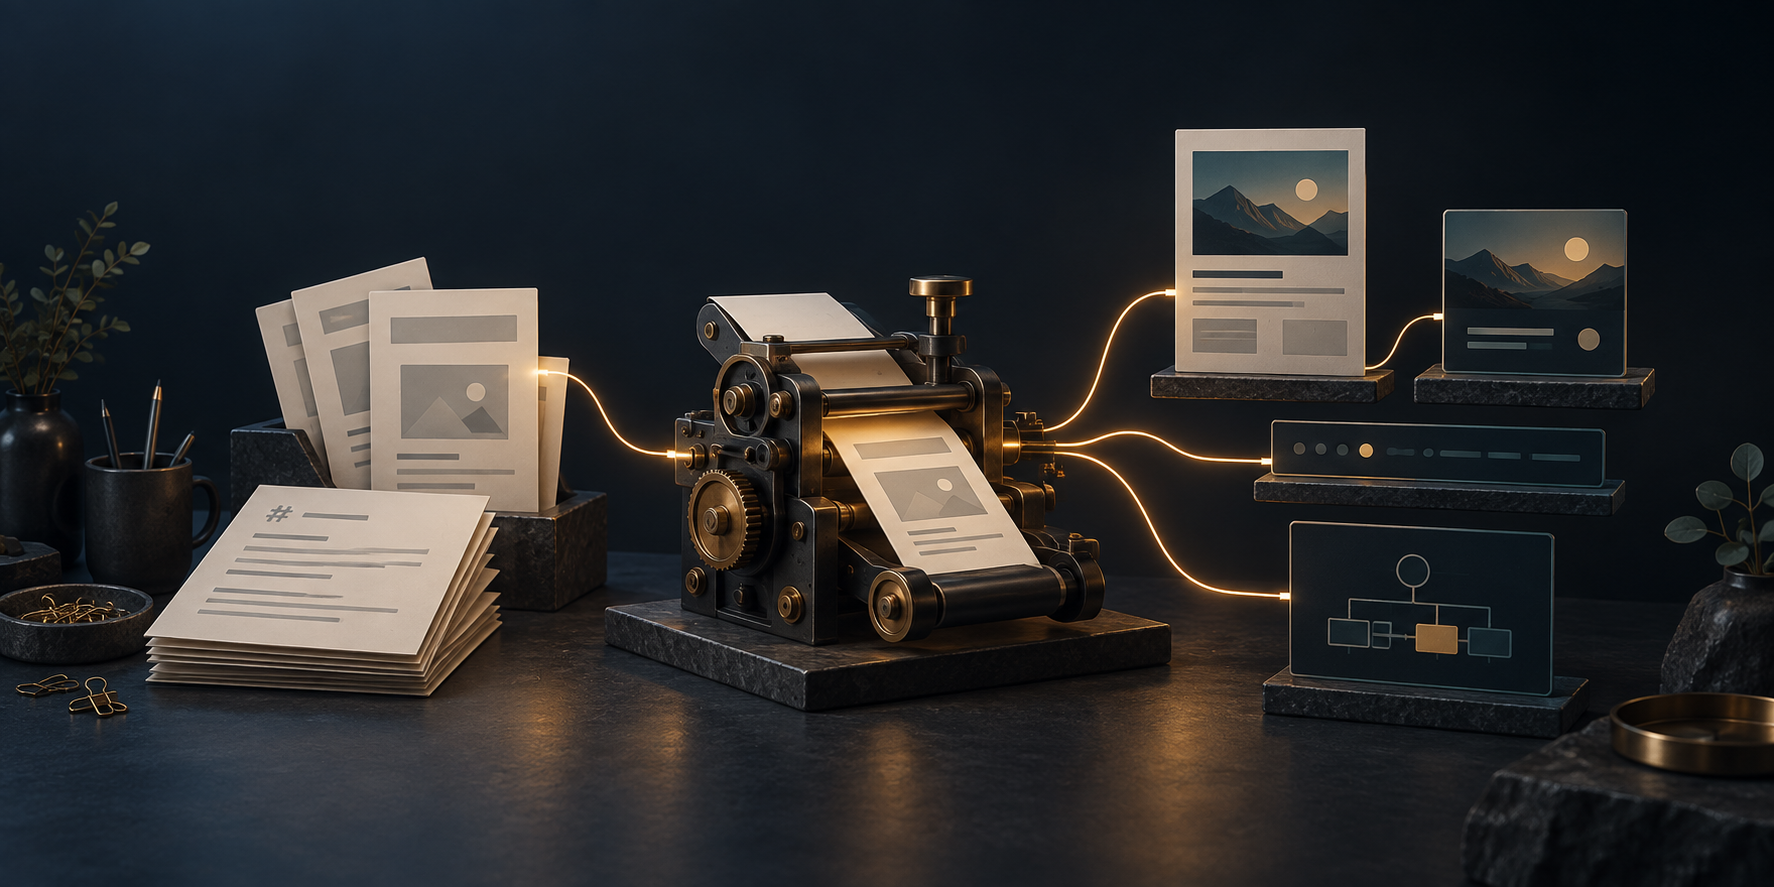
Jekyll was driving me nuts. I could write an article in Markdown, but writing the article was only one part of putting it on the site. A project needed a place in the directory, a landing page, a blog, an image, and a menu entry. A post needed the right metadata and a URL I could live with. A draft dated for next week needed to be visible to me without appearing on the public site. Fixing one thing could expose a different problem in a layout, a link, or the generated pages.
I did not sit down with a plan to build a publishing platform. I kept running into concrete problems and extending the Jekyll site to deal with them. The result is still a static website, but the work around that static output has become a connected publishing workflow.
The First Fix Was Reuse
The site’s history shows that the problem started well before the current collection of utilities existed. Early entries in the changelog describe inconsistent blog display, project blogs that needed a standard directory structure, and post templates that needed to work across the site. A shared blog list, project directories, and common layouts were practical responses. Soon afterward, layout variables, dates, and home-page pagination needed more corrections.
Those entries are a record of changes, not evidence that everything arrived in one release or that each dated entry was deployed that day. They do show the pattern: solve the immediate publishing problem, then discover what needs to be shared so the next page does not require the same repair.
The useful Jekyll lesson was its hierarchy. A project landing page uses the project layout, which uses page, which uses default. The default layout supplies the site’s common shell. The project layout looks up the project in generated data, shows its details, and calls the same blog-list machinery used elsewhere to find that project’s posts. The header includes navigation, and navigation reads the project data too.
Once those relationships were in place, adding a project stopped meaning “edit every place where the project should appear.” The landing page, project index, menu, and project blog can each present the same project through a different shared component. I still have to make editorial decisions, but I no longer have to reproduce the whole page structure by hand.
A Project Starts as Data, Then Becomes Pages
The project catalog is a YAML list of repositories and authored overrides. It lets me describe a project once, including how it should be presented. The data generator can fetch repository information, combine it with my overrides, create or reuse a local project card, and write the generated catalog that Liquid reads during the site build. If a project’s landing page does not yet exist, the same path can scaffold its page, blog directories, and starter material.
That starter material is an invitation to write, not a finished article. A generated introduction is draft-marked, and I still need to replace its generic text and check its metadata before publication. The distinction matters. Automation can give a new project the right home without deciding what I should say about it.
The catalog also has presentation choices. Public projects can have repository links. A private project can have a public description and project blog without exposing a repository link. An entry marked none is left out of the project lists and navigation inspected for this series. Those values decide how this site presents a project; they do not create access control over generated files.
Originally I used GitHub’s OpenGraph thumbnail graphics. Rate limiting made that an awkward dependency, so I started generating project cards locally from repository metadata. The generator can reuse a card when its metadata has not changed and can fall back to other images when needed. It still fetches project information where available. The point was to make the visual presentation more dependable, not to pretend the site had become completely independent of outside data.
That project path is a good example of what I mean by a publishing workflow: authored configuration, generated data, static pages, shared Liquid templates, and editorial review all have different jobs. The site becomes easier to manage when those jobs are explicit.

One project definition reaches several views through generated data and shared templates.
Readers Need More Than One Way Through the Work
Projects are only one route into the writing. A project has its own blog. The main blog has focused sections. A series has a reading order that may differ from publication date. There is also a complete archive for someone who wants to browse across those boundaries. Shared includes filter and render the lists, add excerpts and source labels, and provide pagination.
Even “newest” needs a decision. I can make a substantial update to an older article and have it appear again in discovery without changing its original publication date or its place in a series. The archive uses that effective discovery order, so calling it a strict list by original publication date would be misleading. Meanwhile, the Technology page keeps standalone Technology articles separate from series entries, although those articles retain their category and URLs.
This is where static-site work starts to feel less static. The output is HTML, but the questions are editorial: Where should a reader encounter this article? What is its source? Which order helps them understand the series? What should stay stable when the source files move?
Stable links became especially important as the repository grew. Project posts now carry an explicit slug for the public URL, with redirects for older title-derived paths. Short links can use an immutable source identity that survives a directory move. Those two mechanisms solve different problems, and neither excuses casual changes to a published date or other URL-defining metadata. Once a link has been shared, it is part of the publication, not just a side effect of a filename.

For project posts, the source location, canonical URL, and short redirect have separate identities.
The Tools Around the Build Grew for a Reason
The changelog records more small problems: future-dated posts that were hard to review, URL-encoded links that a checker mishandled, an image path that worked poorly across cases, a missing build plugin, and redirects that did not line up with the URLs the site actually generated. Some attempts were reversed, including a Sass migration that did not work cleanly with the Jekyll converter in use. That history is useful because it shows that extending a site includes knowing when to back out a change.
Today I have a local Jekyll wrapper for builds and previews. Its normal serve mode includes future, draft, and unpublished material for editorial work; a --current mode omits those inclusion flags. Both are local development views. A production build is a separate path. That separation lets me review work that is not yet meant to appear publicly while still asking what the published site will contain.
I also use checks around commits and system maintenance. They do not all do the same thing. Some inspect; others refresh project information, repair content, stage generated files, or replace build output. The GitHub Pages workflow runs a production build and selected URL and taxonomy checks before deployment. I will trace those paths in detail later in the series, because describing all of them as one magical “pre-commit pipeline” would hide the decisions and side effects that matter when something fails.
A successful build also cannot tell me whether a public page, redirect, image, or external link still works after deployment. That is why the repository has separate crawling and site-reliability tools. I will examine what those tools actually check and how they are invoked later in the series. Their existence in the repository alone does not prove that a schedule is running or that every public route is healthy.
Technical Writing Needed Its Own Presentation
The site carries engineering articles, so an article may need more than text and a hero image. I want a diagram to fit in the article and still be readable at full size. I want a source file to be readable in place and available for download. The source disclosure uses the downloadable artifact itself for its highlighted view, which avoids keeping a second code excerpt in sync. That is a presentation guarantee; whether a companion program works still needs its own review.
I also started listening to rendered articles. Hearing a paragraph can reveal a clumsy rhythm or repeated phrase that I missed on the screen. The local proofreader extracts the article prose and lets me listen without making every transient audio chunk a published asset. Retained narration is a separate decision: it has an identity manifest, freshness checks, and an explicit front-matter opt-in after I have reviewed the MP3.
Reader response has its own modest path. Posts can show a GitHub Discussions comment area through Giscus, and the contact page offers a form that opens a prepared message in the visitor’s mail client. The form does not store submissions on the site. I chose those routes rather than building an account and message database for a small publication. So far, I have not seen people use the discussion route. That does not make it a failed infrastructure project; it means I should describe it as a way to respond, not as an established community.
Current State
The site now combines a YAML project catalog, generated project data, reusable Liquid layouts and includes, project blogs, series and archive views, stable-link rules, technical-article presentation, local proofreading, checks, deployment, and monitoring tools. These pieces grew in response to specific publishing needs. They are not all one automatic process, and a few older utilities remain in the repository without being part of how I work today.
The useful result is that Jekyll gives me static output while the surrounding tools make the work of producing it easier to inspect and repeat. Human choices still determine what a project says, whether an article is ready, and when it should go live.
Next Work
The next article starts with the daily question behind much of this tooling: how do I preview a future post or a draft while keeping a clear view of the site as readers will see it? From there I will work through shared templates, project data, URL identity, technical assets, listening, validation, and post-publication checks one problem at a time.
Join the Discussion
Comments for this post live in GitHub Discussions. That keeps moderation in one place and gives the conversation a stable home.